Two papers can study the same concept while measuring different things. If you copy only their variable names, you can miss differences that change how their findings should be compared.
Reliable research data extraction captures measurement details alongside each variable, including its definition, instrument, units, timing, and source location. That record helps you distinguish comparable evidence from results that need separate treatment.
Start by separating what researchers want to understand from what they actually observe.
Separate Constructs, Variables, and Measures
A construct is the concept; a variable is the recorded attribute
A theoretical construct is an idea such as depressive symptom severity, academic engagement, or socioeconomic status. Researchers need an operational definition before they can collect data about it.
A variable is an attribute that takes different values across people, groups, or observations. Depressive symptom severity might become a questionnaire total score, a binary screening classification, or a clinician rating.
Record the variable's role separately. An outcome, predictor, covariate, mediator, and moderator describe different roles in an analysis. The same recorded variable can have different roles across models, so don't assign its role from its name alone.
The instrument or procedure produces the measurement
An instrument is the questionnaire, test, sensor, or other tool used to collect information. A procedure specifies how researchers administer, score, or derive it.
For example, the Patient Health Questionnaire-9 (PHQ-9) contains nine items about symptoms during the previous two weeks. Its total score ranges from 0 to 27.
Here, depressive symptom severity is the construct, PHQ-9 total score is the variable, and the questionnaire plus scoring procedure produces the measurement.
A reported mean score is a result, not the variable itself. Keep variable definitions, measurement methods, and numerical findings in separate fields.
Define Your Extraction Scope Before Reading
Your research question determines which details belong in your data extraction forms. In systematic reviews, extracting everything creates unnecessary work, while capturing only headline findings loses context needed for interpretation.
For intervention questions, including reviews of randomized controlled trials, the PICO framework identifies the population, intervention, comparator, and outcomes. Add study design and measurement timing to interpret those outcomes properly.
The Cochrane Handbook's data collection guidance includes participants, interventions, comparators, and outcomes among essential study characteristics.
Set the unit of extraction
Use a study-level record for design, setting, recruitment, and sample characteristics. Then create a separate measurement record for each variable, group, and time point.
This structure prevents repeated measurements from disappearing inside one oversized cell.
Link reports from the same study
A study may have a main article, protocol, supplement, and follow-up publication. Assign one study identifier and separate report identifiers.
Otherwise, you risk counting the same participants twice or mistaking a later report for an independent study.
Build a Reusable Variable Extraction Table
A literature review matrix often uses one row per source. Detailed measurement extraction usually needs more rows because one paper can contain several outcomes and assessment occasions.
You can maintain the measurement table in Excel or another data extraction tool. For broader source organization, a structured literature review matrix can sit alongside it.
Use these fields for each measurement record.
Field | What to record |
|---|---|
Study and report IDs | Stable identifiers, citation, and source filename |
Construct | Concept the authors intend to investigate |
Variable and role | Exact variable name and role in the relevant analysis |
Operational definition | What values mean and how the variable is defined |
Instrument or procedure | Name, version, language, administration, and scoring method |
Units and scale | Measurement units, possible range, categories, and score direction |
Group and sample | Study arm, subgroup, and analyzed sample size |
Time point | Assessment timing relative to baseline or intervention |
Result and statistic | Effect size or other value, statistic type, and uncertainty estimate |
Source location | PDF page, printed page, section, table, row, or footnote |
Evidence and status | Supporting passage; reported, unclear, or not reported |
Review trail | Extractor, checker, date, and reconciliation decision |
Record effect sizes and uncertainty estimates consistently to support later evidence synthesis or meta analysis.
Preserve the authors' terminology in one field and your standardized label in another. This lets you compare studies without erasing differences in their definitions.
Also maintain a short codebook describing every field and its permitted values. If you change a definition halfway through extraction, revisit earlier records.
Research on developing and testing extraction forms emphasizes their connection to later appraisal, analysis, and synthesis.
Find Measurement Details Beyond the Abstract
Abstracts rarely provide enough information for reliable extraction, so verify details in the full texts. Begin with the methods, then inspect results tables, supplements, protocols, and table footnotes.
Search for instrument names and terms such as "assessed," "scored," "operationalized," "adjusted," and "follow-up." Treat search results as navigation aids, and read the surrounding passage before recording a value.
Capture units, scales, and timing exactly
For physical measurements, preserve units such as kilograms, millimeters of mercury, or milliseconds. For questionnaires, record the possible range, response options, and whether higher scores indicate better or worse outcomes.
Distinguish a total score from a subscale, standardized score, or threshold-based classification. Keep endpoint values separate from change scores, too.
Record timing relative to a defined event. "Three months after enrollment" and "three months after treatment completion" describe different assessment schedules.
Make every entry easy to locate
Save both PDF and printed page numbers when they differ. For numerical results, add the table number, column heading, row label, and relevant footnote.
NotebookLama's cited PDF question-answering can help locate candidate passages. Open the cited page and verify that it supports the exact field you're filling.
Pilot, Extract, and Reconcile the Records
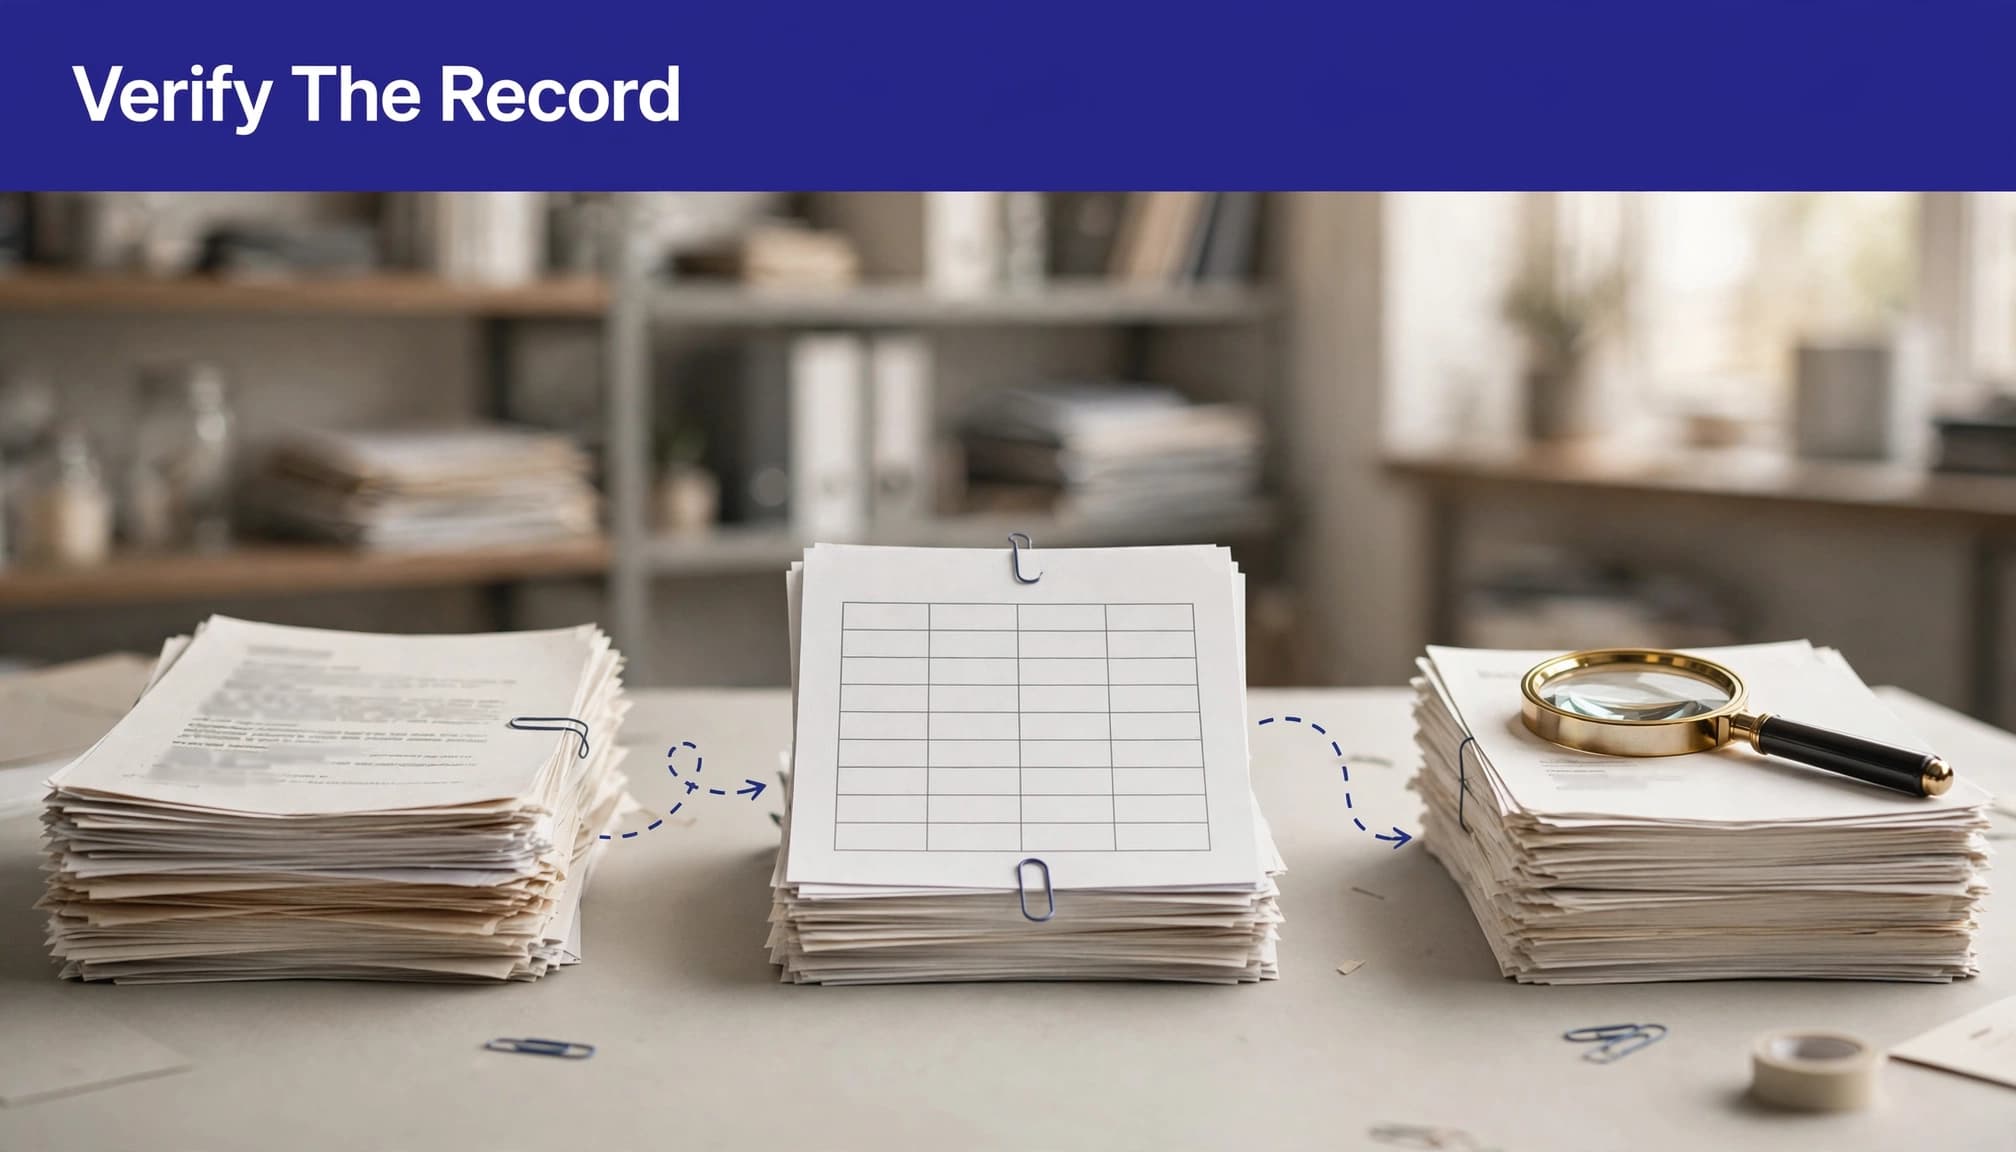
A reliable extraction process has five stages: planning, piloting, extraction, reconciliation, and export. Each stage should leave a record another researcher can inspect.
Pilot the form on contrasting papers
Test the form on several papers with different designs or reporting styles. Include a paper with repeated measurements or a complex results table.
Check whether two readers interpret the fields consistently. Confusion about "sample size," for example, may reveal that you need separate fields for recruited, randomized, and analyzed participants.
Revise the form and codebook before full extraction. Then retain the pilot records so you can see what changed and why.
Compare independent entries before exporting
For systematic reviews, independent extraction by two reviewers is preferable when resources allow, especially for numerical outcomes in randomized controlled trials. Compare their entries before either reviewer sees the other's decisions.
Cochrane's standards for collecting study data connect structured forms with consistency and duplicate extraction.
Resolve disagreements against the source and codebook. If disagreement persists, involve another reviewer rather than averaging incompatible values. Risk-of-bias appraisal is a distinct review task when required by the protocol.
Before export, check required fields, duplicate records, scale ranges, group labels, and effect-size entries against the source. Keep separate copies of extracted data, reconciled data, and later analysis transformations, and verify effect sizes before applying transformations.
Record Uncertainty Instead of Filling Gaps
Use explicit status values such as "Reported," "Not reported," "Unclear," and "Conflicting reports." A blank cell doesn't show whether information is missing or extraction is unfinished.
If authors name an instrument but omit its version, record the name and mark the version as not reported. Don't infer the version or scoring rule from another paper that used the same instrument.
A familiar instrument name doesn't establish which version, translation, scoring rule, or cutoff this study used.
When passages conflict, preserve both statements and their locations. Document how you resolved the conflict, including any rule or clarification used. For important missing details, consider contacting the authors.
Keep reviewer calculations, including any derived effect size, separate from reported values. Retain the original value, formula, and assumptions for each calculation.
For scanned PDFs, check for OCR errors such as missing minus signs, dropped decimals, and confusion between zero and the letter O. Also distinguish standard deviation from standard error, percentages from proportions, and recruited participants from analyzed participants.
For systematic reviews, the PRISMA 2020 reporting checklist supports transparent reporting of collection processes and data items under the PRISMA guidelines. Reporting guidance doesn't replace an extraction protocol.
Use AI for Candidate Extraction, Then Verify
Natural language processing and machine learning can flag candidate passages about populations, interventions, and outcomes. These automation methods can help large language models propose structured entries from supplied text.
However, fluent output can combine information from different groups, confuse background citations with the current study, or invent missing measurement details. Extraction from abstracts may miss details found only in full texts, tables, or supplements. Check every candidate entry against its source throughout the extraction process.
Constrain the source and output
Define your columns before using AI. Start with one paper at a time, and request fields in the same order as your form.
A focused instruction is:
"Use only this paper. Identify each outcome variable, its definition, measurement method, units, assessment timing, and source location. Mark absent details as 'Not reported' and ambiguous details as 'Unclear.'"
Don't upload restricted or sensitive documents unless institutional rules and the service's privacy terms permit it. Check access, retention, and deletion controls.
Evaluate fields, not the polish of the summary
Compare candidate entries against a manually checked sample. Measure both incorrect entries and missed information.
Assess precision and recall. Precision is how many extracted items are correct; recall is how many relevant items the system finds. Neither replaces checks of units, time points, group assignment, and source support.
An Excel spreadsheet can manage a small project. Larger reviews may need data extraction tools such as Covidence, RevMan, or DistillerSR; repeated scanned tables may need OCR and parsing. Software examples don't replace source verification.
After verification, cross-document PDF comparison can help surface measurement differences. Recheck those comparisons against individual sources before treating variables as equivalent.
Key Takeaways
Separate the construct, recorded variable, measurement method, and numerical result.
Preserve units, scale definitions, group membership, timing, and precise source locations for every measurement record.
Keep missing or conflicting information visible, and verify AI-generated entries before they enter your reconciled dataset.
The strongest extraction table supports both comparison and correction. Another reader should be able to reconstruct each entry without repeating your entire search.
Frequently Asked Questions
What is the difference between a construct, a variable, and a measure?
A construct is the concept researchers want to understand, while a variable is the recorded attribute used to represent it. A measure is the instrument or procedure that produces the recorded value.
What details should I record for each variable?
Record its operational definition, role, instrument or procedure, units or scale, group, assessment timing, and source location. Keep reported results separate from variable definitions and measurement details.
What should I do when a measurement detail is missing or unclear?
Use an explicit status such as “Not reported” or “Unclear,” and do not infer details from another study. Preserve conflicting statements with their source locations and document how you resolved them.
Can AI extract research data reliably?
AI can identify candidate passages and propose entries, but it may confuse groups or invent missing details. Verify every entry against the full text, tables, or supplements before adding it to the reconciled dataset.
Build an Extraction Record You Can Defend
Reliable research data extraction preserves how each value was produced and where it came from. Shared variable names alone don't make results comparable.
Start with a defined form, pilot it, and keep source-linked records through verification and reconciliation.
When a paper leaves a measurement detail unclear, preserve that uncertainty. A visible gap is more useful than a confident assumption that distorts the evidence.